Member of Technical Staff · Skild AI
Saketh
Rambhatla
These days I’m teaching robots to do useful things at Skild AI. Before that I spent three years at Meta getting AI to dream up images and video, like Movie Gen and Emu Video.
Selected work
All 23 papers →Movie Gen: A Cast of Media Foundation Models
Foundation models that generate HD video with synchronized audio, plus instruction-based video editing and personalized video generation.
Emu Video: Factorizing Text-to-Video Generation by Explicit Image Conditioning
State-of-the-art diffusion-based text-to-video generation by first generating an image, then a video conditioned on it.
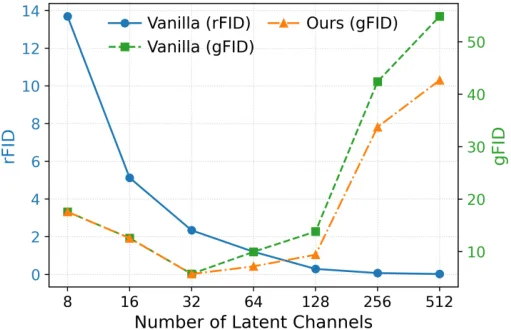
Toward Diffusible High-Dimensional Latent Spaces: A Frequency Perspective
Why higher-dimensional autoencoder latents improve reconstruction but eventually hurt generation, studied through a frequency lens.
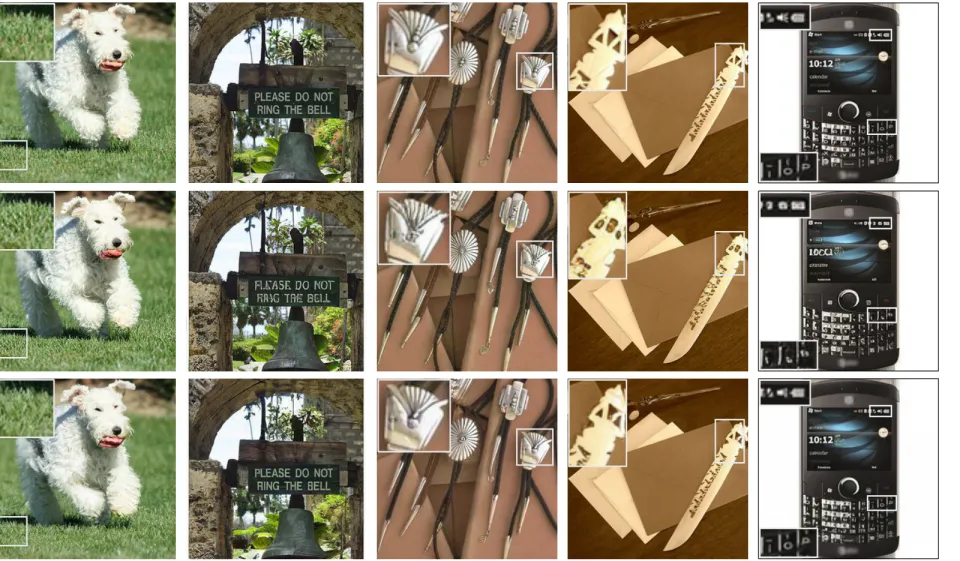
Diffusion Autoencoders are Scalable Image Tokenizers
DiTo: a simple diffusion tokenizer that learns compact visual representations for image generation with a single learning objective.
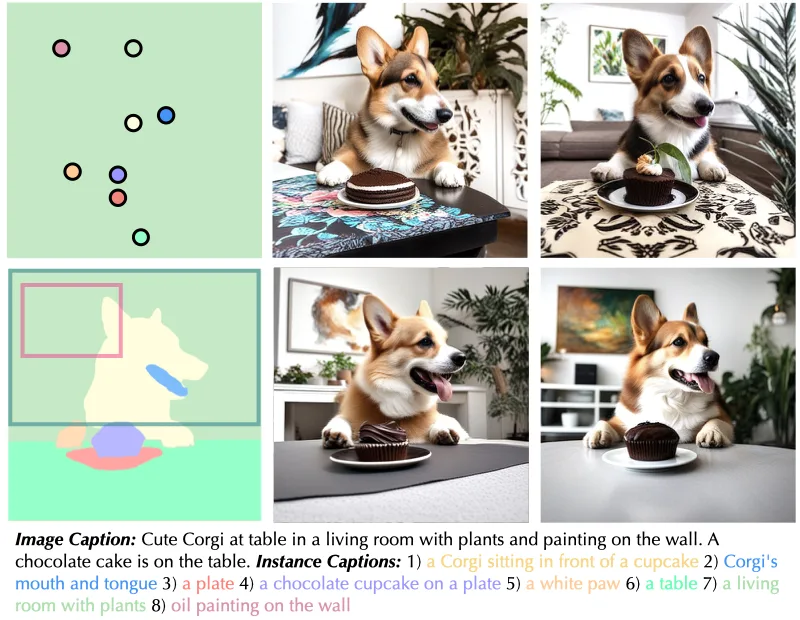
InstanceDiffusion: Instance-level Control for Image Generation
Precise instance-level control — points, boxes, scribbles, masks — for text-to-image generation.